Why You (Probably) Shouldn’t Start Your Project with Microservices
Microservices were mostly invented to scale teams, not traffic. If you don’t have the team problem yet, a modular monolith is probably the wiser place to start.
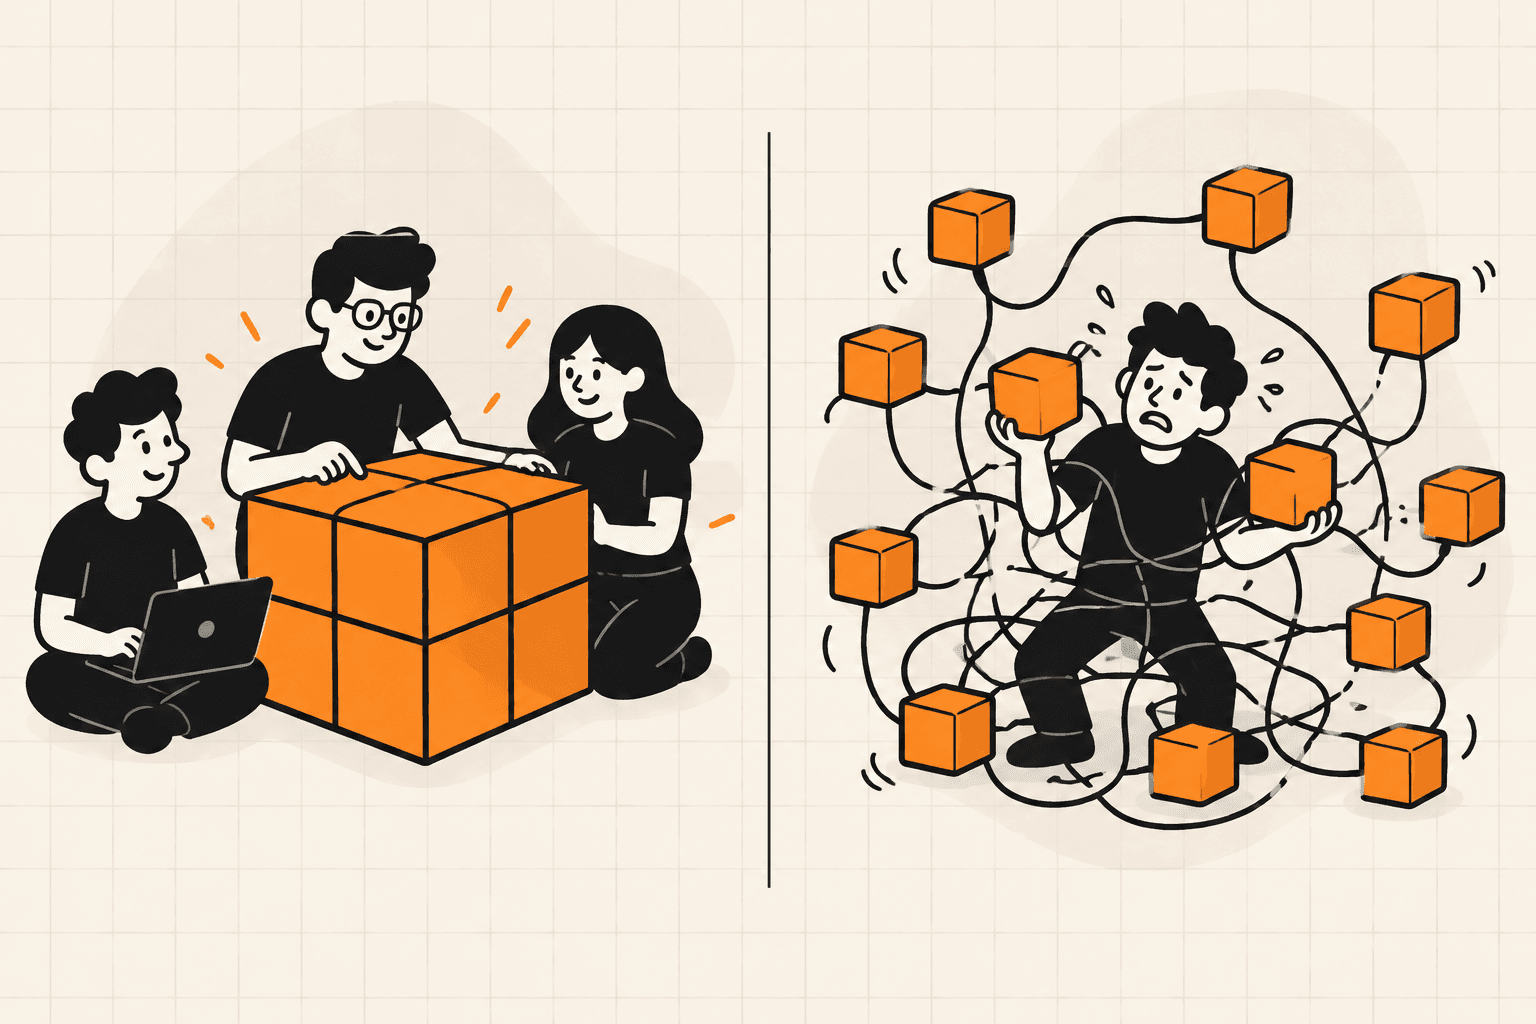
Let’s be honest: if you’ve browsed job posts or followed tech influencers recently, you’ve probably felt a bit of FOMO. Everyone’s talking about microservices, Kubernetes, event-driven architectures, distributed tracing, and enough acronyms to fill a startup pitch deck. It almost feels like if your system isn’t built on microservices, you’re doing it wrong.
I used to think of microservices mainly as a way to scale software: more users, more traffic, more services. Then, in a software architecture class, my professor said something that changed how I look at the whole topic:
Microservices weren’t created to solve a software scalability problem. They were created to solve a people scalability problem.
The more I dug into it, the more it made sense. And once you look at microservices that way, it becomes much clearer why starting a new project with them usually brings more pain than gain.
What microservices were actually for
Back in 1968, Melvin Conway published a paper called How Do Committees Invent?, with an observation that became known as Conway’s Law: organizations that design systems end up producing designs that are “copies of the communication structures of these organizations.”
In other words, software tends to be split the way the company is split, not necessarily the way that makes the most sense for the software. Put three teams on a compiler and you’ll get a three-pass compiler.
When James Lewis and Martin Fowler wrote the article that popularized the term microservices in 2014, Conway’s Law was right there in the argument. Their point was that instead of splitting teams by technology (a UI team, a backend team, a database team), you organize them around business capabilities, and each small team owns its service end to end. The article even points to Amazon’s “two-pizza team” rule as a reference for size: if two pizzas can’t feed the team, it’s too big.
Think about what that solves. When a hundred engineers work on the same codebase, they constantly step on each other’s toes: merge conflicts, long release trains, one team’s bug blocking everyone else’s deploy, endless coordination meetings. Microservices give each team something they can change, test, and deploy on their own. Sam Newman, author of Building Microservices, puts independent deployability at the center of the whole idea, and that is fundamentally an organizational benefit.
To be fair, my professor’s statement is a bit of a simplification. Lewis and Fowler also list scaling individual services independently as a benefit, and that’s real if one part of your system has very different load than the rest. But a monolith can scale too: you can run more copies of it behind a load balancer, and most systems never outgrow that. What a monolith really struggles with is letting dozens of teams move independently. That’s the problem microservices are best at solving.
No team problem, no need for the team solution
This is where it clicked for me. If microservices are primarily a solution for organizational scale, what happens when you adopt them without that organization?
If you’re a team of four (or a team of one), you don’t have a hundred engineers stepping on each other. You have four people who can talk to each other across the table. Splitting the system into twelve services doesn’t give you team autonomy, because there are no separate teams to make autonomous. It just means each developer now maintains three services, and every feature touches several of them at once.
You end up with Conway’s Law in reverse: an architecture far more fragmented than the organization that maintains it. And very often, the result is a distributed monolith, services that can’t really be deployed independently because they’re all tightly coupled, with all the complexity of a distributed system on top.
Microservices come with a bill
Every microservice needs:
- Its own codebase or at least its own deployable unit
- Its own database (sharing one defeats much of the purpose)
- Its own CI/CD pipeline
- Its own monitoring, logging, and tracing
- A communication strategy (REST, gRPC, messaging...)
- Infrastructure to run it all: containers, service discovery, retries, failover
And a function call that used to be instant and reliable is now a network call that can be slow, fail, or time out. Transactions that used to be a single database commit now span services and need patterns like sagas or eventual consistency.
Large organizations pay this bill gladly because the alternative, hundreds of engineers fighting over one deploy pipeline, is even more expensive. For an early-stage product, it’s mostly overhead. Your biggest priority should be shipping quickly and validating your idea, not building a distributed system worthy of a Netflix tech talk.
You don’t know the boundaries yet
There’s another reason to wait. Microservices force you to decide where the boundaries of your system are, and those decisions are expensive to change later. Moving a piece of logic from one module to another in a monolith is a refactor. Moving it from one service to another is a migration, with APIs, data, and deploys to coordinate.
In the beginning, the business domain is a moving target. You’re still figuring out what the product even is. If you split the system too early, you’ll likely draw boundaries that don’t match the real business responsibilities, and you’ll pay for that with every new feature.
This is exactly the argument behind Martin Fowler’s Monolith First: almost all the successful microservice stories he’d seen started with a monolith that got too big and was broken up, while systems built as microservices from scratch often ran into serious trouble.
Monoliths aren’t the villain
A monolith is just a system where everything runs in the same process: customer registration, order processing, reporting, all bundled up. Traditionally, you’ve got one codebase, one deployable, and one database.
That comes with real advantages:
- Easy to build, test, debug, and deploy
- Refactoring across the whole system is just a refactor
- Can scale vertically (more CPU/RAM) and horizontally (more replicas behind a load balancer)
And real drawbacks, which show up as you grow:
- Hard to scale just one part of the system differently from the rest
- Without discipline, components get tangled together
- Collaboration bottlenecks when too many developers share the same codebase and release cycle
Notice that the last one is exactly the people problem microservices were designed for. If you don’t have it yet, the remaining trade-offs lean heavily in the monolith’s favor.
Even big companies sometimes go back. In 2023, Amazon’s Prime Video team moved their audio/video monitoring service from a distributed, serverless design into a single process and cut that service’s infrastructure cost by more than 90%. That doesn’t mean Amazon is abandoning microservices, but it’s a good reminder that distributing a system is a choice with a price, not a default.
The smarter path: modular monoliths
Here’s a better approach: start with a modular monolith.
Instead of one big ball of code, you structure your application as modules, each with a clear responsibility. Ideally, these modules follow the bounded contexts of your domain, a concept from Eric Evans’ Domain-Driven Design: areas of the business that are cohesive and self-contained.
For example, in an e-commerce system:
- A module for Product Catalog
- Another for Order Management
- One for Payments
- And so on
Each module can have:
- Its own domain model and business rules
- Its own tests
- Its own schema, even within the same database
- A clear public interface, so other modules don’t reach into its internals or its tables
That last point is what makes it work. You get the simplicity of a single deployable, with boundaries that are real enough to be enforced, and cheap enough to move while you’re still learning the domain.
And when the time comes, you can extract a module into a service. Cleanly, because the boundary already exists.
Split when your teams need it
So when should you move to microservices? My professor’s point gives a pretty good rule of thumb: when your teams start getting in each other’s way, not when you imagine how much traffic you might have one day.
If you have several teams that need to ship independently, if releases are blocked by coordination, if one module has very different scaling or reliability needs than the rest, then extracting services starts paying for itself. If you’re building a startup MVP, a side project, or a client system with a small team, start with what’s simple and sustainable.
Build a modular monolith. Learn the domain. Deliver value. Split when your organization needs it.
That’s how software grows with your understanding, and with your team, instead of collapsing under complexity it never needed.